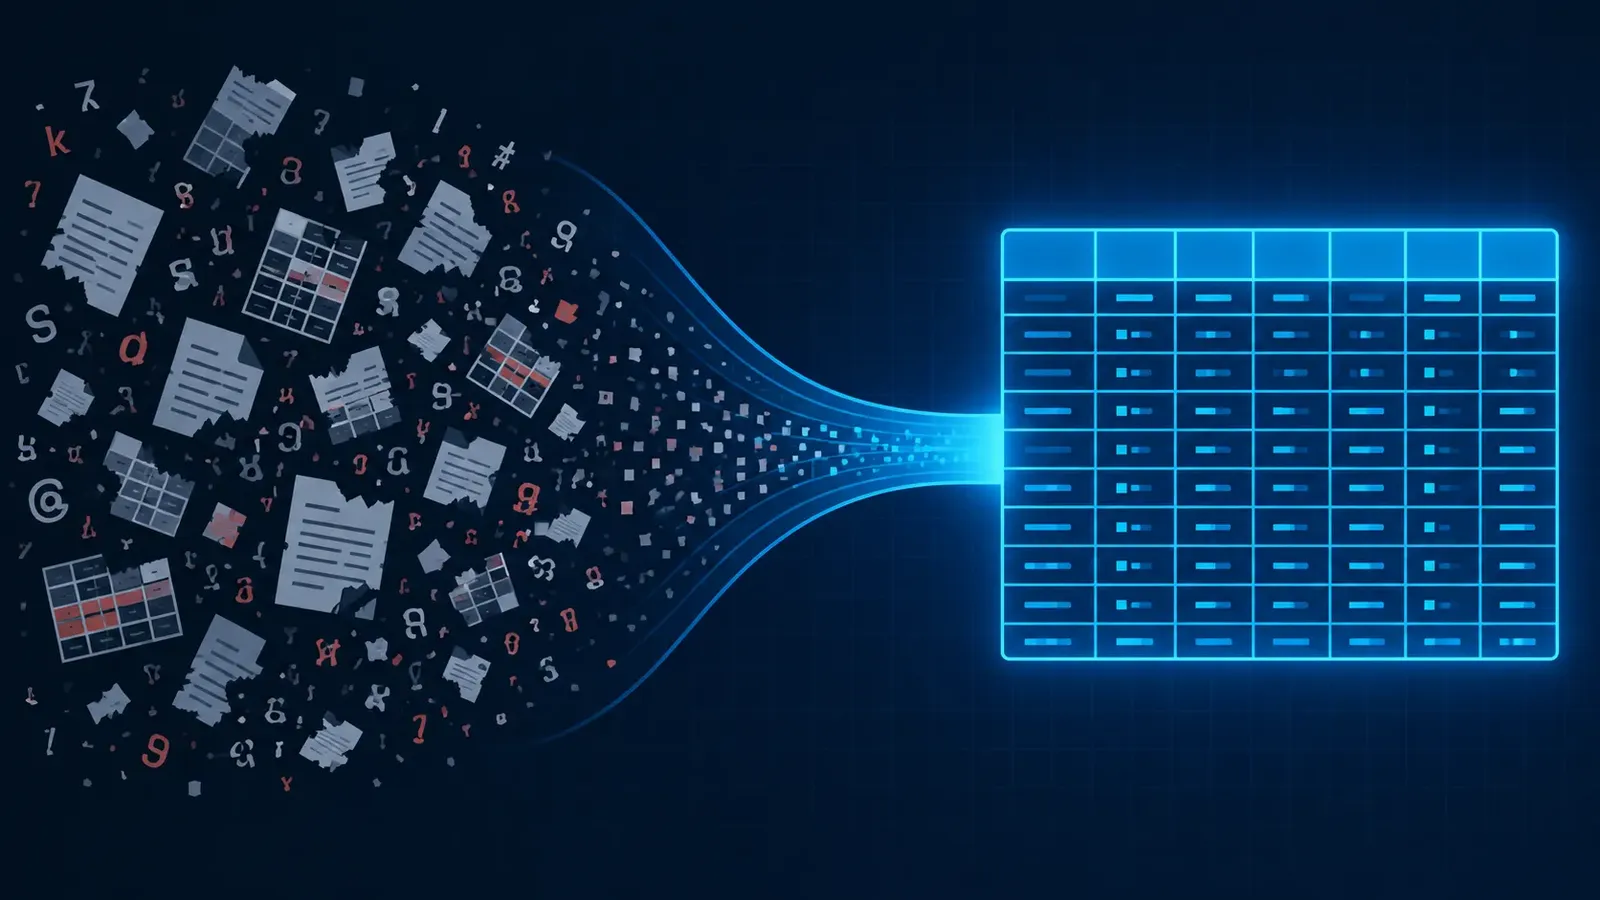
Overview
Every RAG tutorial starts the same way: load a clean PDF, split it into 500-character chunks, dump it in a vector DB, ask a question. It works great on a two-page sample resume.
Point that same pipeline at 10,000 real enterprise documents — scanned PDFs, multi-column research papers, scrambled financial tables, internal wikis — and it falls apart. The model hallucinates with confidence. Numbers get attached to the wrong products. Retrieval accuracy drops below 60%.
There's a line that keeps coming up in AI engineering work, and it's true every time: writing the prompt takes a day, building the vector search takes two days, and cleaning the messy source data takes three months.
Here's the four-stage cleansing pipeline I built to turn chaotic enterprise documents into chunks a retrieval system can actually trust.
The Four Ways Enterprise Data Breaks RAG
Before the fix, the failure modes worth naming:
A["Raw Messy Data"] --> B["1. Scrambled 2D Tables"]
A --> C["2. Dirty OCR & Typo Noise"]
A --> D["3. Multi-Column Layout Bleed"]
A --> E["4. Orphan Chunks (Broken Context)"]
Scrambled tables. Humans read tables in two dimensions. Naive PDF extractors read left to right across the raw bounding box, so a structured financial statement turns into:
"Q1 Revenue Product A $1.2M Q2 $1.4M Product B $500K Margin 24%"The embedding has no idea which revenue belongs to which product.
Dirty OCR noise. Scanned contracts and old invoices are full of compression artifacts. OCR mangles them in predictable ways — SEV-1 becomes 5EV-l, $5,000 becomes $5.000, Form HC-902 becomes Form HC-9O2. Once the tokens are corrupt, both vector and keyword search fail.
Multi-column layout bleed. In two-column documents — academic papers, corporate bylaws — a naive parser reads straight across the page and interleaves two unrelated sentences into one chunk.
Orphan chunks. A chunk that says "the submission deadline is within 48 hours" is useless on its own if the chunk before it — the one with the actual policy name — got cut off during splitting.
The Fix: Decouple Cleansing From Retrieval
The pattern that actually works is separating data cleansing and normalization from the retrieval engine entirely. Retrieval only ever sees data that's already passed through four stages:
Messy["1. Raw Dirty Data\n(PDFs, HTML, Scans)"] --> S1["Stage 1: Rule-Based Cleansing\n(Regex, ftfy, Boilerplate Strip)"]
S1 --> S2["Stage 2: Structural Reconstruction\n(Layout Parsers & Table Markdown)"]
S2 --> S3["Stage 3: Semantic SLM Repair\n(Fast OCR & Heading Normalization)"]
S3 --> S4["Stage 4: Deduplication & Quality Gate\n(MinHash & Token Density Filter)"]
S4 --> Clean["Pristine Markdown Chunks\n(Ready for Vector & BM25 Indexing)"]
Stage 1: Deterministic Rule-Based Cleansing
Before touching any model, run fast, deterministic heuristics:
- Unicode normalization (`ftfy`) — fixes corrupted encoding, like turning
—back into a real em dash. - Boilerplate stripping — repeated headers,
"Page 12 of 84", cookie disclaimers. All regex, all cheap, all pollution if left in. - Hyphenated linebreak collapse — recombines words split across lines:
import re

def clean_hyphenation(text: str) -> str:
    # Turns 'con-\n tract' into 'contract'
    return re.sub(r'(\w+)-\n\s*(\w+)', r'\1\2', text)
Stage 2: Structural and Layout Reconstruction
This is where tables and multi-column PDFs actually get fixed. Basic text extractors can't do this — you need vision-based layout parsers like Docling or LlamaParse, which treat the page as a 2D visual grid: they identify table borders, columns, and merged cells, then convert the visual table into an explicit Markdown table.
| Incident Severity | Definition | Acknowledgment SLA | Status Page Cadence |
|---|---|---|---|
| SEV-1 (Critical) | Complete service outage (>10% users) | < 5 minutes | Every 15 minutes |
| SEV-2 (Major) | Core feature broken (p99 > 5,000ms) | < 15 minutes | Every 30 minutes |
Once a table looks like this, the row-column relationships survive the embedding step intact.
Stage 3: Semantic Repair via Small Language Models
For OCR-corrupted text, a fast, lightweight model — something like Llama-3.2-3B or Gemini Flash — does the repair:
System Prompt:
"You are a document normalization engine. Fix obvious OCR character misrecognitions
(e.g., '5EV-l' -> 'SEV-1'). Preserve all numerical values, codes, and proper nouns verbatim.
Output clean Markdown with hierarchical headings."
At roughly 100ms per pass, the SLM turns noisy text into clean, searchable Markdown without touching the underlying facts.
Stage 4: Deduplication and Quality Filtering
The last gate before anything reaches the database:
- Near-duplicate detection (MinHash / SimHash) — if HR uploaded four revisions of the same leave policy, only the latest survives.
- Information density filter — chunks under ~20 meaningful words (empty signature blocks,
....... 42table-of-contents dots, isolated URLs) get dropped.
Connecting Clean Data to Retrieval
Once the corpus is clean and tagged with metadata — document ID, title, section IDs — it feeds a hybrid retrieval setup: dense vectors for meaning, BM25 for exact codes, and a cross-encoder reranker to sort the fused candidates.
CleanDocs["Pristine Markdown Corpus"] --> Chunker["Semantic Chunker (Distance Shifts)"]
Chunker --> VDB["ChromaDB (Dense Vector Search)"]
Chunker --> BM25["BM25 (Sparse Keyword Index)"]
Query["User Query: 'What is Form HC-902 used for?'"] --> Search["Hybrid Search (Vector + BM25)"]
VDB & BM25 --> Search
Search --> Candidates["Top 20 Fused Candidates"]
Candidates --> Reranker["Cross-Encoder Reranker (FlashRank)"]
Reranker --> Top3["Top 3 Pristine Chunks (Score: 99.88%)"]
Top3 --> LLM["Generation LLM + Verified Citations"]
On a 50-question ground-truth benchmark, the gap between the naive baseline and this pipeline is not subtle:
| Pipeline Stage | Hit Rate @ 3 | MRR | Exact Code Match |
|---|---|---|---|
| Naive baseline (raw PDFs, fixed 500-char chunks) | 61.2% | 0.52 | Failed on codes |
| Clean data + semantic chunks | 74.5% | 0.68 | Partial |
| Clean data + hybrid (BM25 + vector) | 82.1% | 0.76 | 100% |
| Clean data + hybrid + FlashRank reranker | 92.4% | 0.89 | Pristine |
Retrieval quality is capped by parsing quality. No reranker fixes a table that was scrambled on the way in.
What I'd Tell Anyone Building This
- Never feed raw PDFs straight into a vector DB. Every downstream layer inherits whatever the parser got wrong.
- Use a layout parser for tables, always. Explicit Markdown tables preserve column context that flat text extraction destroys.
- Pair BM25 with dense vectors. Vector search is great for meaning; it's bad at exact codes like
HC-902orSEV-1. BM25 catches what embeddings miss. - Reranking is the highest-ROI layer. A lightweight cross-encoder running locally in ~15ms took this pipeline from 80% to over 92% precision — for less engineering effort than almost anything upstream of it.
The code, the 50-question evaluation harness, and the local ChromaDB/BM25 setup are on GitHub. If you're building RAG on messy internal documents: which of these four failure modes has bitten you hardest — tables, OCR, layout bleed, or orphan chunks?
CONNECTED / NEXT
Keep exploring
Related work from across this engineering knowledge system.
Why Direct Text-to-SQL Is Broken in Production
The pattern works great on ten rows of mock data. Here's why it falls apart the moment real users touch it.
OPEN →
I Gave My LinkedIn Posts a Memory — Here’s What Happened
How Model Context Protocol, a local SQLite second brain, and the official LinkedIn API let any AI client draft, remember, and publish posts.
OPEN →
Comments